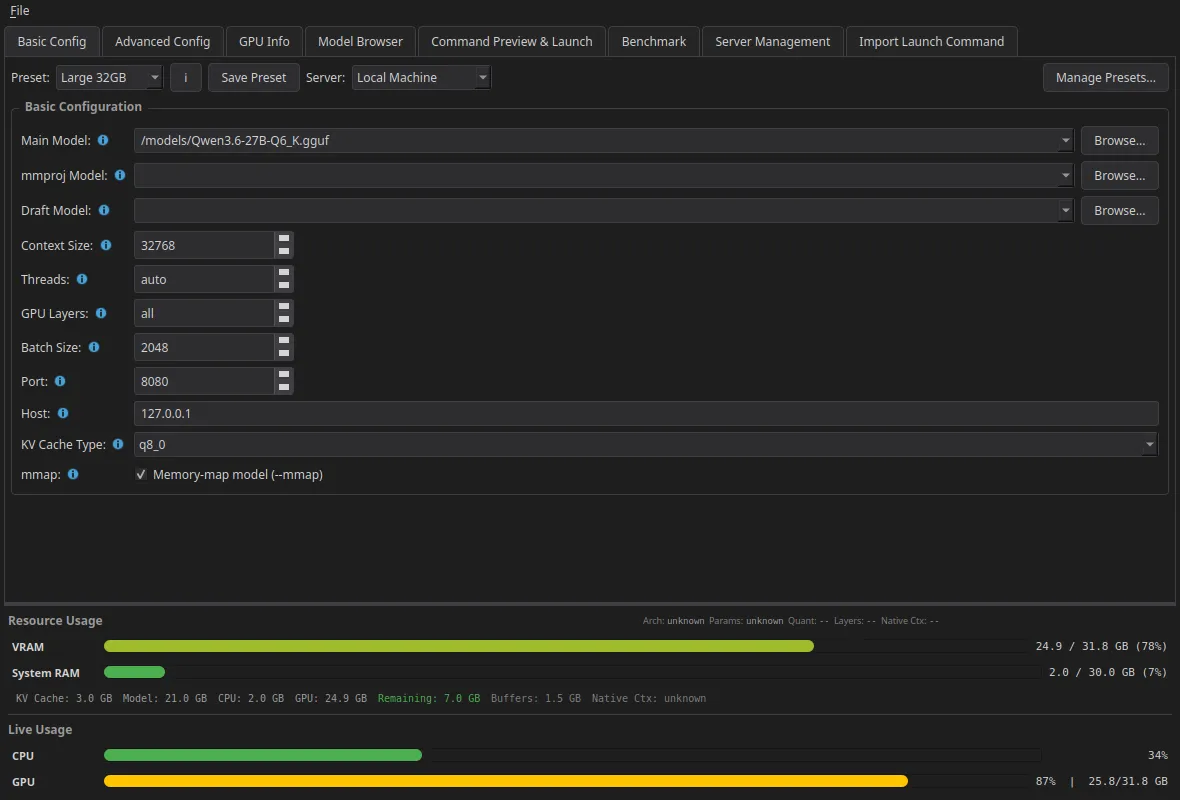
Running a local model with llama.cpp means remembering dozens of flags, and the right ones change with every build. llama-launcher turns that into a form: pick a model, choose a preset or tune the parameters, read the exact command it will run, and launch. Every flag in its registry is checked against the real llama-server binary, so the settings it suggests actually exist.
It knows your hardware. NVIDIA, AMD (with or without ROCm), Apple Metal and Vulkan are detected, VRAM and RAM are predicted from the GGUF file itself to within about one percent of what llama-server allocates, and the GPU tab shows live utilization, temperature and which processes are holding memory.
The same window manages servers on other machines over SSH: status, logs, a file browser and a one-click key install. Benchmarks are parsed straight from the server logs and tied to the preset that produced them.