Local AI systems
Private AI that never leaves the building.
We design, build and configure AI systems that run entirely on your own hardware: a single workstation tuned for llama-server, or a GPU cluster serving a whole company. Your models, your data, your machines. Local inference, local data, nothing in the cloud.
AI workstation
A custom-built PC around an RTX 5090-class GPU, with the right CPU, memory and NVMe for the models you want to run. It arrives configured: drivers, llama-server, a chat interface, and presets chosen for its VRAM. Plug in, sign in, ask a question.
AI cluster
When one box is not enough: several RTX 5090 workstations, DGX Spark units, or Dell servers with NVIDIA or AMD GPUs, serving models side by side with shared storage, load balancing and remote management. Sized to your users and your models, not a catalogue.
Configure what you have
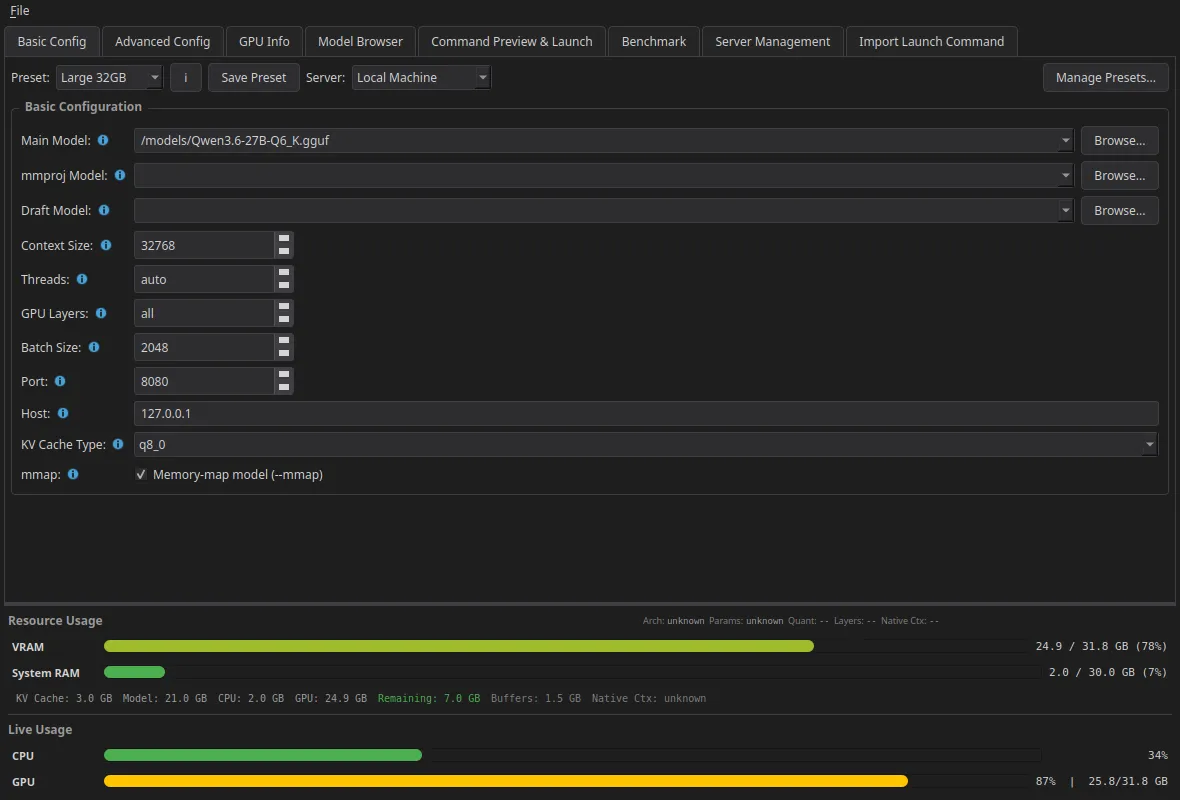
Already own the hardware? We make it earn its keep: CUDA or ROCm set up properly, the right llama.cpp build, quantizations that fit, context sizes that hold, and presets verified against the real binary. This is the work llama-launcher came out of.
Why local
Keep the intelligence where the data is.
Local inference
Prompts, documents and answers never leave your network. Nothing is sent to a cloud API, so nothing can be logged, trained on or subpoenaed elsewhere.
Local data
Point the system at your own files, databases and knowledge: it reads them where they live. Air-gap it entirely if you need to.
Predictable cost
Hardware you own instead of a per-token bill that grows with success. Run it flat out all day; it costs the same.
Real hardware, real numbers
Every build is benchmarked on the actual models you will run. You get the throughput figures before you sign off, not a brochure estimate.
What you get
A system, not a parts list.
- Hardware specification and sourcing
- Build, burn-in and thermal testing
- OS, drivers, CUDA or ROCm
- llama-server and a web chat front end
- Models selected and quantized for the VRAM
- Benchmarks: tokens per second, per model, documented
- Backups, updates and remote management
- Documentation and hand-over, with support after
Hardware we work with
- Workstations: NVIDIA RTX 5090 and 4090-class GPUs, single or multi-GPU, on platforms with the memory bandwidth to feed them.
- Compact clusters: NVIDIA DGX Spark units, or racks of RTX workstations networked for shared serving.
- Servers: Dell PowerEdge with NVIDIA data-centre GPUs or AMD Instinct accelerators, CUDA or ROCm.
- Software: llama.cpp / llama-server, open-weight models (Llama, Qwen, Mistral, Gemma and more), web chat front ends, retrieval over your documents, and llama-launcher to manage it all.
We run this gear ourselves. Benchmarks and VRAM estimates come from our own machines, not spec sheets.
Request a quote
Tell us what you want to run.
How many people will use it, which models or tasks matter, and whether anything must stay fully offline. We come back with a recommended configuration, benchmarks for comparable builds, and a price. No obligation.
- ✓ Canadian, bilingual
- ✓ We reply within two business days
- ✓ Your data never has to leave your site, even during setup